
From 18 months to six minutes: Emma Fisher on the future of systematic reviews
A professor of paediatric pain at the University of Bath is running Kasvu Discovery’s Systematic Review feature against reviews she has already published, to see whether it includes the same studies, excludes the same studies, and reaches the same risk-of-bias judgements.
Ten thousand abstracts came back from the last search update alone.
That was for a single systematic review: one that ran to 113 included studies and took five years from first protocol to publication this June. Across her wider portfolio, Emma Fisher has had projects that required screening 30,000 to 40,000 abstracts. Every one of them read by a person, sorted into include or exclude, one at a time.
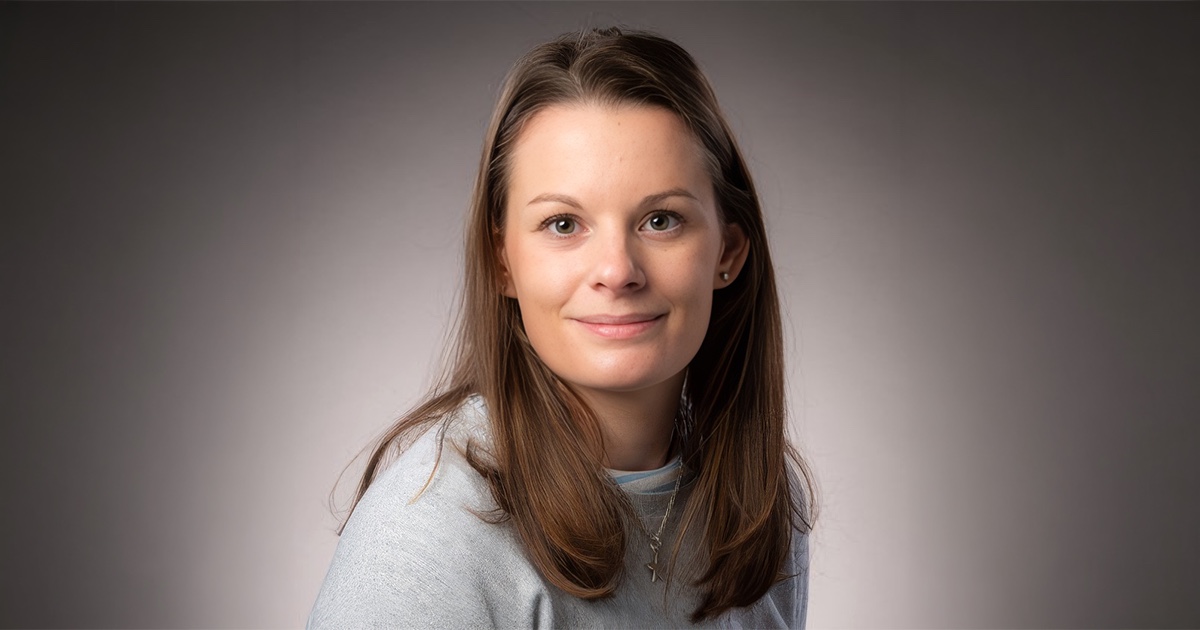
Fisher is Professor of Paediatric Pain and Evidence-Based Medicine at the University of Bath. Her work centres on how children experience pain and what can be done about it, and she builds her treatment thinking around three pillars: pharmacological, psychological, and physical interventions that can make pain better. Her group also runs projects on risk factors between acute and chronic pain in children after injuries, perceived injustice in children with cancer-related pain, blast injuries in Ukraine, and menstrual pain interventions in Nepal, investigating pain and influences of pain across high and low resource settings.
She is, in other words, someone whose time has obvious better uses than reading abstracts day after day. I had the pleasure of speaking with her on September 8th about her experience with the systematic review process, both with Kasvu Discovery and without.
What the labour actually consists of
Anyone who has run a systematic review can recite the sequence. Design and test the search strategy across the databases. Run it. Pull the results into a reference manager and de-duplicate. Then read: titles and abstracts, thousands of them, applying the inclusion and exclusion criteria consistently on Friday afternoon exactly as you applied them on Monday morning. Retrieve the full texts that survive. Decide which to include and exclude. Discuss disagreements with other authors. Extract the data. Assess risk of bias. Judge the quality of evidence. Write it up and publish before your search lapses in relevance.
Almost none of this is intellectually difficult, but it is relentless, and the cognitive load is where the cost sits – both in months and in the quality of attention a reviewer has left by the end. This is why Fisher has been moving that workflow onto the Systematic Review feature in Kasvu Discovery. The search, screening and extraction steps that previously took between six and 18 months now run in under six minutes.
I realise this figure needs stating carefully, and I would rather state it carefully than have a methodologist do it for us. It measures elapsed processing time for a workflow, not a finished review, and it is not yet a claim about equivalence. Whether the output of those six minutes matches what a human team produced over those 18 months is the open question – and it is the question Fisher is currently working on.
What the Systematic Review feature does
The Kasvu systematic review feature develops a search strategy from a user-inputted research question and inclusion-exclusion criteria. This can be refined by the user to ensure it captures what they want and need. It then executes the search across databases, de-duplicates, screens titles and abstracts against the inclusion and exclusion criteria, and gives the user a list of abstracts that it is unsure about for the user to decide if it should be included or excluded. Development is ongoing to extract data from the studies that are included, and can apply risk-of-bias tools to them.
However, the feature is currently optimised for randomised controlled trials in pain and psychological interventions. It has not been tested yet for other types of reviews, but the good news is that our team is working on broadening the scope as we speak.
Emma’s not taking the number on trust
Fisher’s first task with the tool is not to use it on anything new. It is to try to catch it out.
She is running it backwards, against systematic reviews that have already been completed and published by human teams (including her own) and checking three things: 1) Does it include the same studies? 2) Does it exclude the same studies? 3) Does it apply the risk-of-bias tools and arrive at the same judgements?
She is starting small: a review of roughly 20 studies on remotely delivered psychological interventions, where the answer set is already known and any divergence is easy to inspect. From there the plan is to scale up to larger network analyses, and to pain interventions that aren’t psychological.
Where the machine can do better than a person
Fisher’s expectation is that the gain won’t only be speed, but increased consistency.
Her example is specific: reviewers miss information when it turns up somewhere they weren’t looking, like randomisation procedures described in the Analysis-section rather than in the Methods, where they typically belong. A human scanning their eight-thousandth paper looks where the information should be. An algorithm has no “should”. The same applies to data buried inside composite measures, such as depression outcomes reported within a broader anxiety scale.
Once the validation holds, Fisher wants to move towards living systematic reviews: weekly automated search updates that notify the user of new studies as they appear.
The case for this is easy to underrate if you don’t work in evidence synthesis. A review is up-to-date on the day it is conducted but is arguably out of date by the time it gets published, typically a year later or even more. Under the current model, a trial that would change the conclusion of a review waits for somebody to find the funding to do the review and the staff to conduct an update. This can take years, during which clinicians, guideline committees, and policymakers are working from an evidence base that everyone knows is out of date and nobody can afford to refresh.
“Excellent supplement to knowledge and a poor replacement for an expert”
In our interview, Fisher raised two excellent points about using AI for this kind of work.
The first is about who ends up doing systematic reviews. To make the process cheaper and accessible, reviews are often produced by people, like undergraduates and students, without the expertise to judge what they are synthesising. Fisher’s position is that AI is an excellent supplement to knowledge and a poor replacement for the expert researcher. She points out that in many areas there are already more systematic reviews than there are trials to review. Lowering the barrier further is not self-evidently a good thing.
The second is that human verification does not go away. Fisher intends to read every full-text paper, and to double-check the extracted data and risk-of-bias assessments until she is satisfied that the AI is consistently reliable. The labour saving is in the screening, not in the judgement.
Reception among her colleagues has split along a line she finds unsurprising: systematic reviewers, who know exactly what the screening burden costs, are considerably more enthusiastic than those who have never done it.
We are speaking to Fisher again in six months to find out how the Systematic Review feature of Kasvu Discovery has fared in her expert hands.
In the meantime, if you are a researcher in a topic we’re not yet covering, do be in touch! We are always looking for co-developers to improve Kasvu Discovery with. Explore the Systematic Review feature and more today!
This interview was conducted by a member of the Kasvu Discovery team in collaboration with the scientists who have helped us build the platform since its inception. We aim to sit down with professionals each month and talk about the different ways Discovery bakes into their workflows. Stay tuned.